The perception front end that improved the map, and the ablation showing where the improvement came from.
2026 · published
The whole pipeline on ScanNet scene 0000. M2H-MX predicts depth and semantics from the image stream, Mono-Hydra++ consumes those predictions inside the visual-inertial odometry and the mapping backend, and the hierarchical scene graph is built in real time. Playback is 16x.
01 — The system
What it does
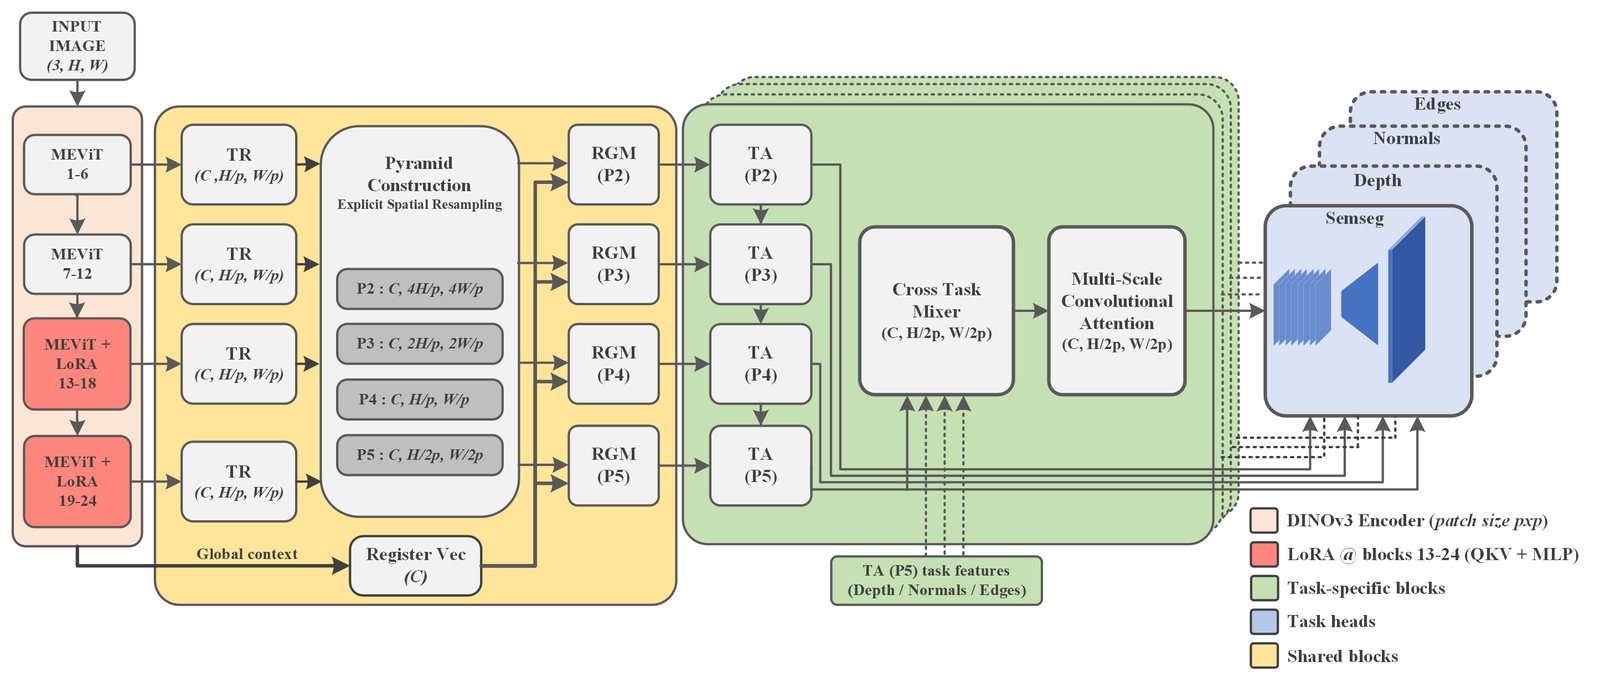
DINOv3 features adapted with LoRA, decoded through register-gated Mamba blocks at multiple scales, with directed cross-task refinement between depth and semantics. Exported to ONNX and TensorRT FP16 for the drone.
Engineering ownership
My contribution
Developed the multi-task perception model and evaluated its predictions inside the mapping pipeline.
Exported and optimised embedded inference through ONNX and TensorRT FP16 on Jetson Orin NX.
A simplified view of the model and its deployment path. ONNX / TensorRT FP16 is the embedded inference route.
02 — Evidence
The whole pipeline on ScanNet scene 0000. M2H-MX predicts depth and semantics from the image stream, Mono-Hydra++ consumes those predictions inside the visual-inertial odometry and the mapping backend, and the hierarchical scene graph is built in real time. Playback is 16x.Watch the full clip
Indoor, NYUDv2
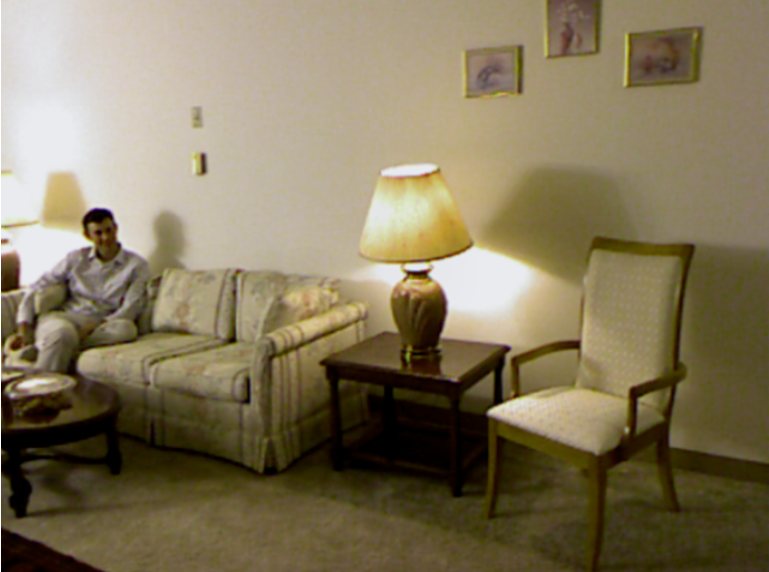
RGB input
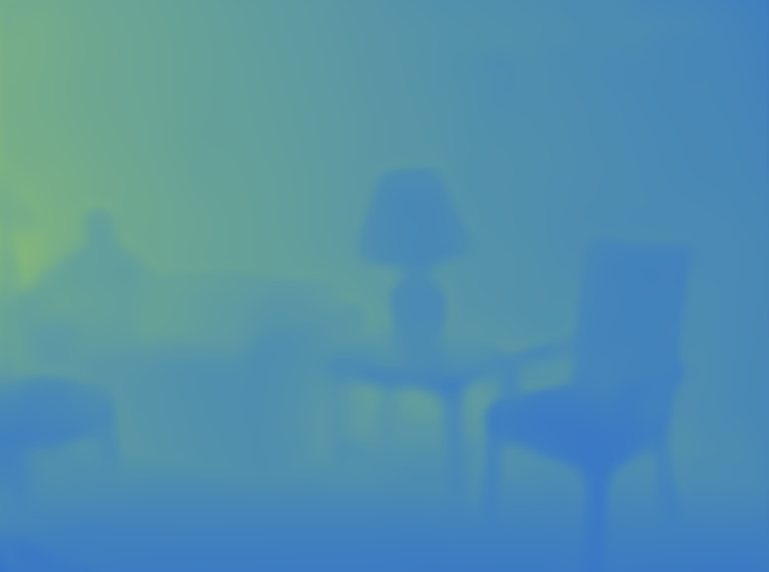
Predicted depth
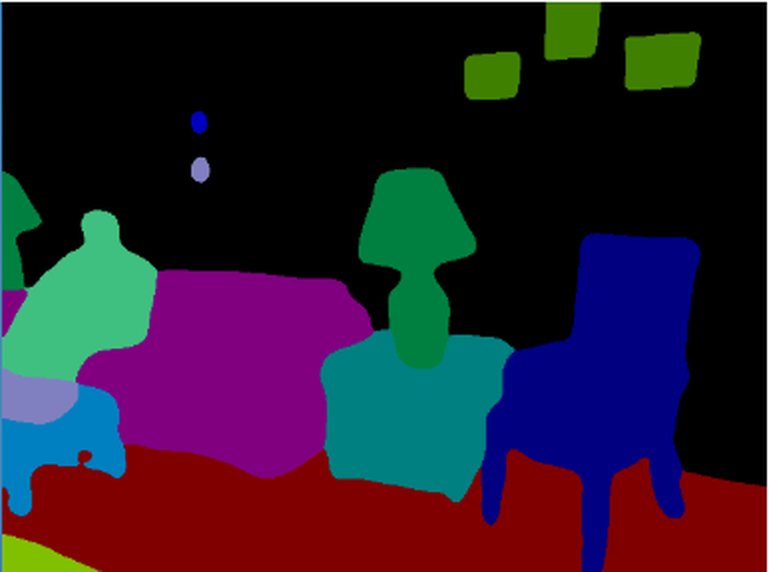
Predicted semantics
Indoor frame, NYUDv2. Metric depth and semantic labels from one RGB image. Pick a layer, or drag to blend between them.
Outdoor, Cityscapes
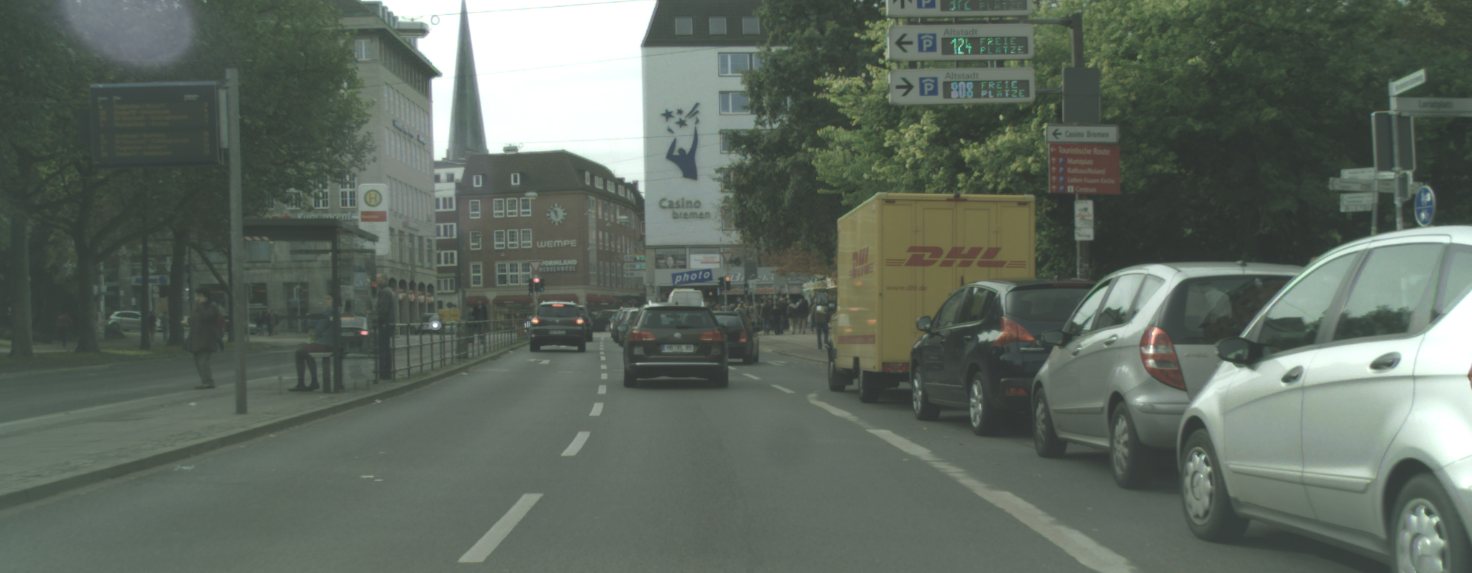
RGB input
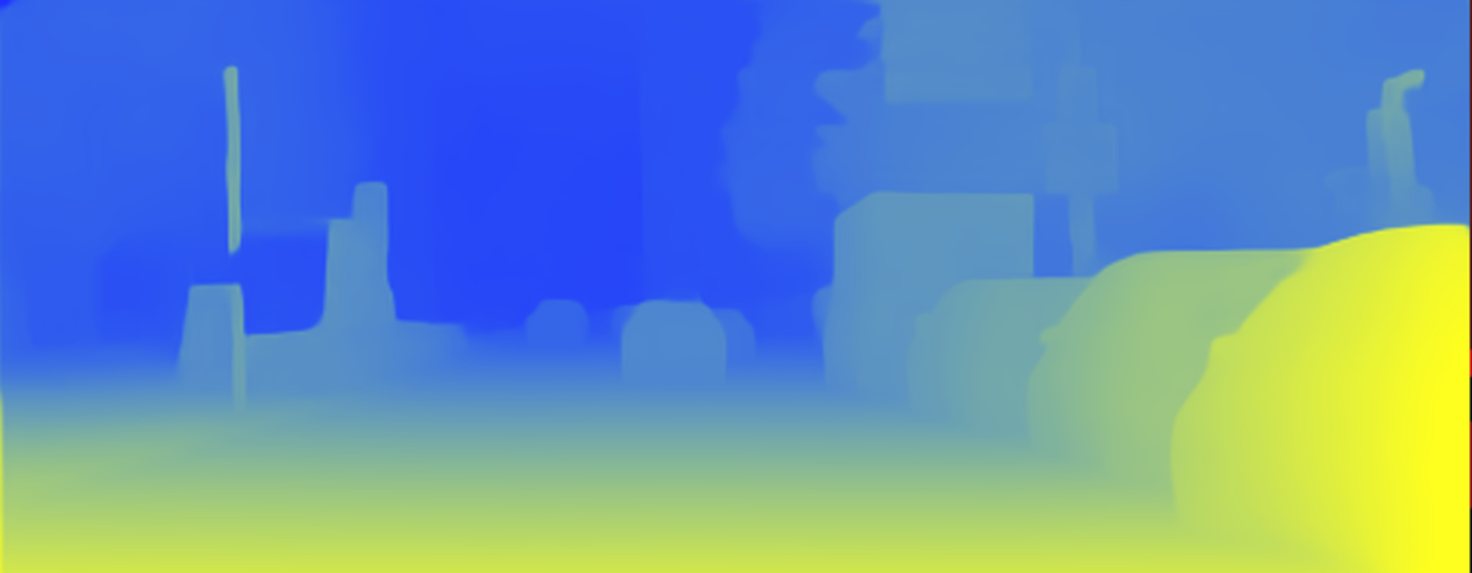
Predicted depth
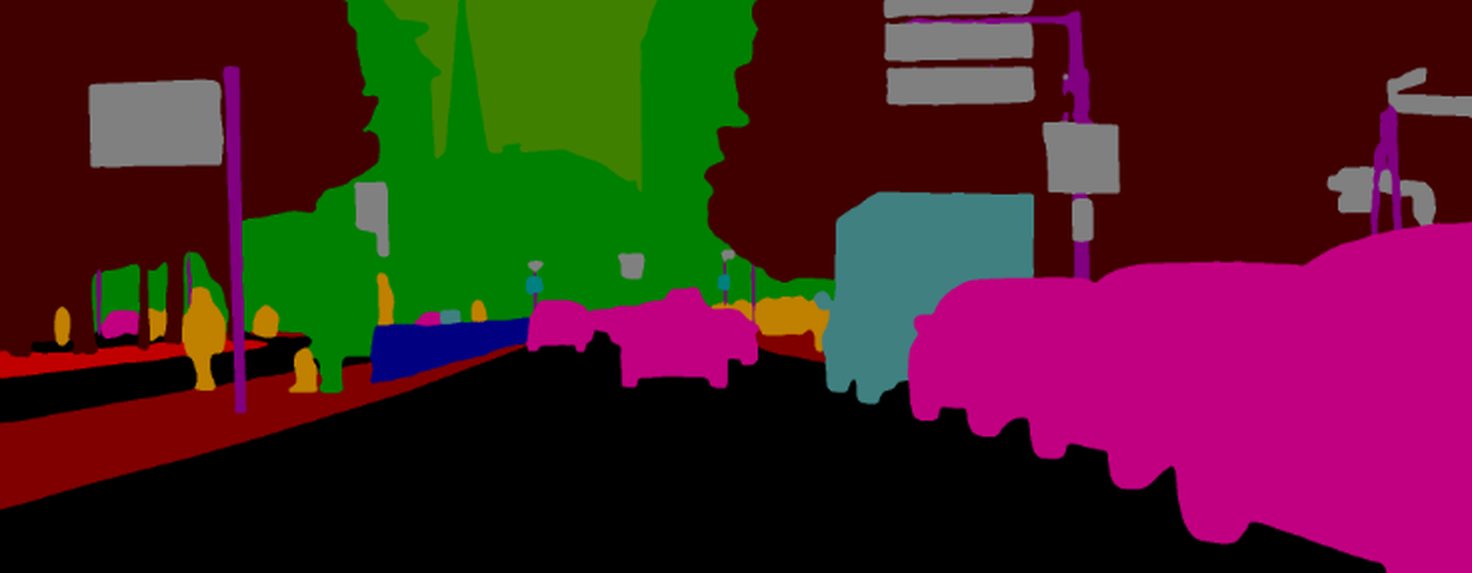
Predicted semantics
The same model outdoors, Cityscapes: 82.28 mIoU, 3.15 points over the strongest baseline. Pick a layer, or drag to blend between them.M2H-MX. The backbone stays mostly frozen and LoRA adapts the later blocks, so the compute goes into the decoder and the cross-task exchange rather than into retraining the features.
Measured
Key numbers
65.60 mIoU and 0.3800 RMSE on NYUDv2
6.91 cm average ScanNet ATE, down from 17.59 cm
25.53 fps on Jetson Orin NX 16GB at 256x192
Every figure here appears in the thesis results registry with
its source location. Conditions are stated with the number.