Projects · Part I
M2H
Four dense tasks in one model, replacing two separate networks that did not agree with each other.
01 — The system
What it does
Window-based cross-task attention on a DINOv2-small backbone, predicting depth, semantics, surface normals, and edges together so that each task can use what the others found.
Engineering ownership
My contribution
- Developed a shared model for depth, semantics, surface normals and edges using cross-task attention.
- Integrated the learned predictions into monocular scene graph construction and evaluated mapping performance.
System sketch
One image, four connected prediction tasks
- 01InputOne RGB image
- 02EncodeDINOv2-small backbone
- 03Share informationWindow-based cross-task attention
- 04Predict togetherDepth, semantics, normals, edges
02 — Evidence
ITC building corridor
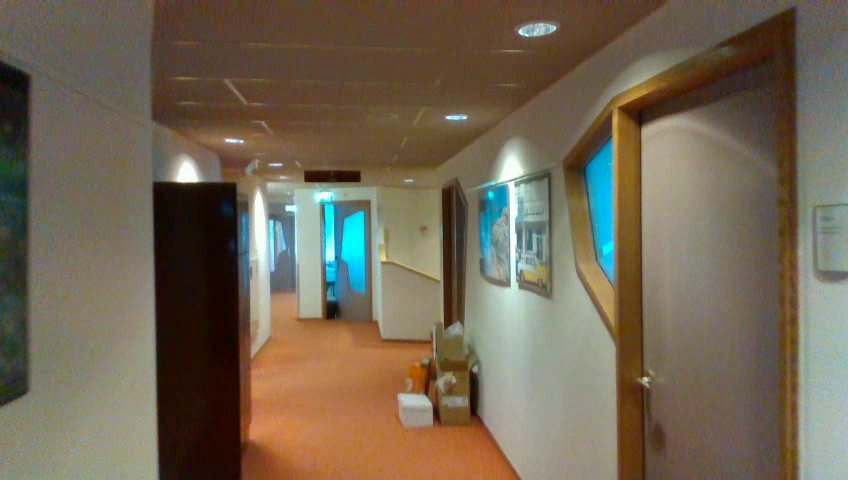
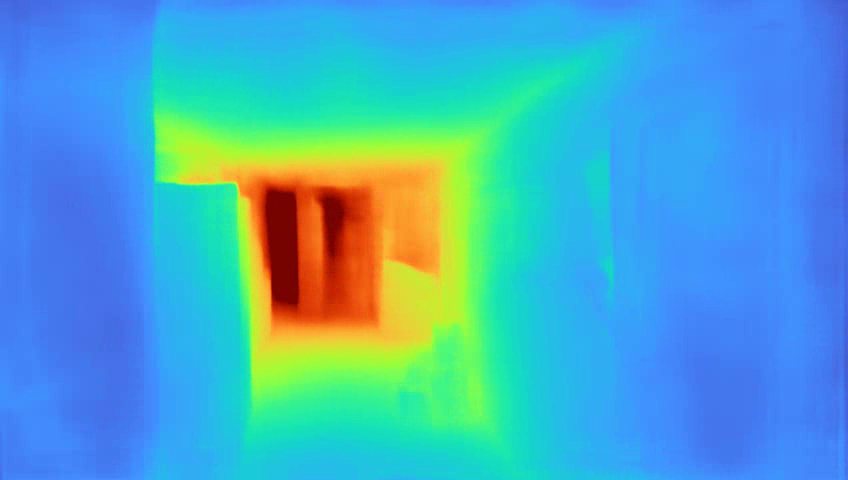
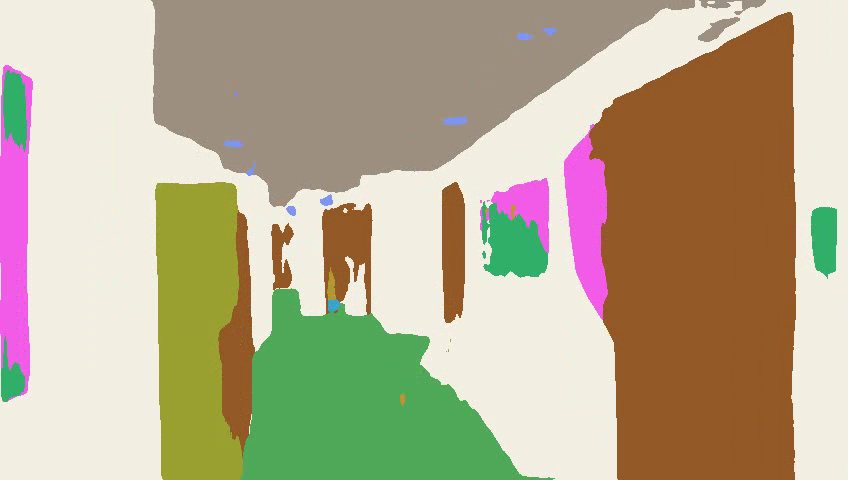
Measured
Key numbers
- 61.54 mIoU and 0.4196 RMSE on NYUDv2
- 0.11 m ITC mean error at 30 fps
- 81 M parameters, 488 GFLOPs
Every figure here appears in the thesis results registry with its source location. Conditions are stated with the number.